

One operational implication of RLVR is that capability is no longer driven only by larger pretraining runs. If reward signals are objectively verifiable, training can shift toward longer optimization cycles, different compute allocation, and a stronger dependence on task design. For teams building or evaluating models, that changes the economics of iteration: the bottleneck becomes less about raw scale and more about how well a problem can be turned into a rewardable environment.
This also raises the bar for architecture around applications and evaluation. When benchmark-like tasks can be optimized directly, scorecards become less reliable as proxies for real-world utility. Enterprises will need narrower, workload-specific validation, plus stronger controls around data isolation, prompt/context handling, and failure detection. The practical trade-off is clear: tighter integration with private systems and feedback loops can improve usefulness, but it also increases coupling between model behavior, internal data, and operational risk.
For developers, the emerging agent and “vibe coding” layer shifts software delivery toward orchestration. The value moves from isolated prompts to workflows that combine reasoning, tools, and iterative review. That favors teams who can design human-in-the-loop processes, keep autonomy bounded, and decide which parts of a system should remain editable, disposable, or fully automated. The result is less like adopting a single model and more like introducing a new runtime pattern into the engineering stack.
1. Reinforcement Learning from Verifiable Rewards (RLVR)
At the start of 2025, the LLM production stack in all labs looked something like this:- Pretraining (GPT-2/3 of ~2020)
- Supervised Finetuning (InstructGPT ~2022) and
- Reinforcement Learning from Human Feedback (RLHF ~2022)
2. Ghosts vs. Animals / Jagged Intelligence
2025 is where I (and I think the rest of the industry also) first started to internalize the “shape” of LLM intelligence in a more intuitive sense. We’re not “evolving/growing animals”, we are “summoning ghosts”. Everything about the LLM stack is different (neural architecture, training data, training algorithms, and especially optimization pressure) so it should be no surprise that we are getting very different entities in the intelligence space, which are inappropriate to think about through an animal lens. Supervision bits-wise, human neural nets are optimized for survival of a tribe in the jungle but LLM neural nets are optimized for imitating humanity’s text, collecting rewards in math puzzles, and getting that upvote from a human on the LM Arena. As verifiable domains allow for RLVR, LLMs “spike” in capability in the vicinity of these domains and overall display amusingly jagged performance characteristics – they are at the same time a genius polymath and a confused and cognitively challenged grade schooler, seconds away from getting tricked by a jailbreak to exfiltrate your data.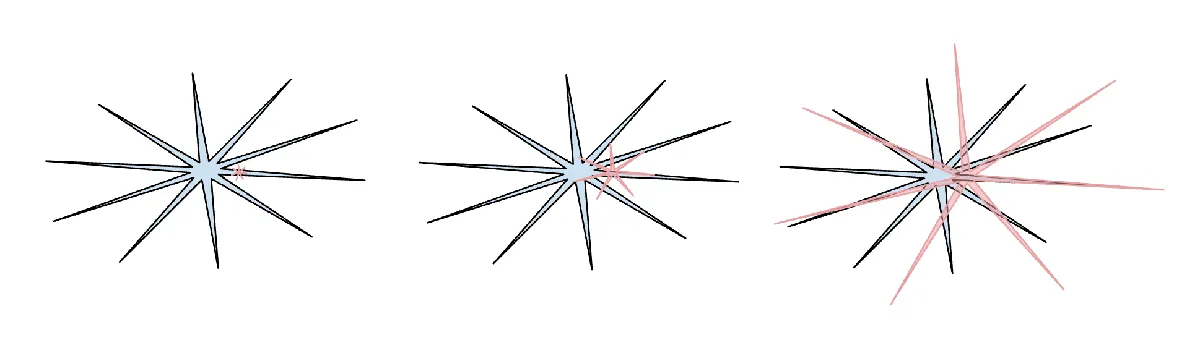 (human intelligence: blue, AI intelligence: red. I like this version of the meme (I’m sorry I lost the reference to its original post on X) for pointing out that human intelligence is also jagged in its own different way.)
Related to all this is my general apathy and loss of trust in benchmarks in 2025. The core issue is that benchmarks are almost by construction verifiable environments and are therefore immediately susceptible to RLVR and weaker forms of it via synthetic data generation. In the typical benchmaxxing process, teams in LLM labs inevitably construct environments adjacent to little pockets of the embedding space occupied by benchmarks and grow jaggies to cover them. Training on the test set is a new art form.
What does it look like to crush all the benchmarks but still not get AGI?
I have written a lot more on the topic of this section here:
3. Cursor / new layer of LLM apps
What I find most notable about Cursor (other than its meteoric rise this year) is that it convincingly revealed a new layer of an “LLM app” – people started to talk about “Cursor for X”. As I highlighted in my Y Combinator talk this year (transcript and video), LLM apps like Cursor bundle and orchestrate LLM calls for specific verticals:- They do the “context engineering”
- They orchestrate multiple LLM calls under the hood strung into increasingly more complex DAGs, carefully balancing performance and cost tradeoffs.
- They provide an application-specific GUI for the human in the loop
- They offer an “autonomy slider”
4. Claude Code / AI that lives on your computer
Claude Code (CC) emerged as the first convincing demonstration of what an LLM Agent looks like – something that in a loopy way strings together tool use and reasoning for extended problem solving. In addition, CC is notable to me in that it runs on your computer and with your private environment, data and context. I think OpenAI got this wrong because I think they focused their codex / agent efforts on cloud deployments in containers orchestrated from ChatGPT instead oflocalhost. And while agent swarms running in the cloud feels like the “AGI endgame”, we live in an intermediate and slow enough takeoff world of jagged capabilities that it makes more sense to simply run the agents on the computer, hand in hand with developers and their specific setup. CC got this order of precedence correct and packaged it into a beautiful, minimal, compelling CLI form factor that changed what AI looks like – it’s not just a website you go to like Google, it’s a little spirit/ghost that “lives” on your computer. This is a new, distinct paradigm of interaction with an AI.
5. Vibe coding
2025 is the year that AI crossed a capability threshold necessary to build all kinds of impressive programs simply via English, forgetting that the code even exists. Amusingly, I coined the term “vibe coding” in this shower of thoughts tweet totally oblivious to how far it would go :). With vibe coding, programming is not strictly reserved for highly trained professionals, it is something anyone can do. In this capacity, it is yet another example of what I wrote about in Power to the people: How LLMs flip the script on technology diffusion, on how (in sharp contrast to all other technology so far) regular people benefit a lot more from LLMs compared to professionals, corporations and governments. But not only does vibe coding empower regular people to approach programming, it empowers trained professionals to write a lot more (vibe coded) software that would otherwise never be written. In nanochat, I vibe coded my own custom highly efficient BPE tokenizer in Rust instead of having to adopt existing libraries or learn Rust at that level. I vibe coded many projects this year as quick app demos of something I wanted to exist (e.g. see menugen, llm-council, reader3, HN time capsule). And I’ve vibe coded entire ephemeral apps just to find a single bug because why not – code is suddenly free, ephemeral, malleable, discardable after single use. Vibe coding will terraform software and alter job descriptions.6. Nano banana / LLM GUI
Google Gemini Nano banana is one of the most incredible, paradigm-shifting models of 2025. In my world view, LLMs are the next major computing paradigm similar to computers of the 1970s, 80s, etc. Therefore, we are going to see similar kinds of innovations for fundamentally similar kinds of reasons. We’re going to see equivalents of personal computing, of microcontrollers (cognitive core), or internet (of agents), etc etc. In particular, in terms of the UIUX, “chatting” with LLMs is a bit like issuing commands to a computer console in the 1980s. Text is the raw/favored data representation for computers (and LLMs), but it is not the favored format for people, especially at the input. People actually dislike reading text – it is slow and effortful. Instead, people love to consume information visually and spatially and this is why the GUI has been invented in traditional computing. In the same way, LLMs should speak to us in our favored format – in images, infographics, slides, whiteboards, animations/videos, web apps, etc. The early and present version of this of course are things like emoji and Markdown, which are ways to “dress up” and lay out text visually for easier consumption with titles, bold, italics, lists, tables, etc. But who is actually going to build the LLM GUI? In this world view, nano banana is a first early hint of what that might look like. And importantly, one notable aspect of it is that it’s not just about the image generation itself, it’s about the joint capability coming from text generation, image generation and world knowledge, all tangled up in the model weights.TLDR. 2025 was an exciting and mildly surprising year of LLMs. LLMs are emerging as a new kind of intelligence, simultaneously a lot smarter than I expected and a lot dumber than I expected. In any case they are extremely useful and I don’t think the industry has realized anywhere near 10% of their potential even at present capability. Meanwhile, there are so many ideas to try and conceptually the field feels wide open. And as I mentioned on my Dwarkesh pod earlier this year, I simultaneously (and on the surface paradoxically) believe that we will both see rapid and continued progress and that yet there is a lot of work to be done. Strap in.
Enjoyed this article? Sign up for our newsletter to receive regular insights and stay connected.