
Together with price-performance, customers want to manage data transformations (SQL Select statements written by data engineers, data analysts, and data scientists) in Amazon Redshift with features including
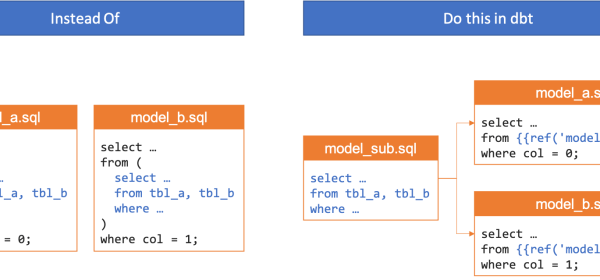
Together with price-performance, customers want to manage data transformations (SQL Select statements written by data engineers, data analysts, and data scientists) in Amazon Redshift with features including

In the last 12 months, Snowflake customers have replicated over 300 PB of compressed data across regions and clouds to keep their businesses up and running. To get started, you use a FAILOVER GROUP, a new

The goal of the solution presented in this post is to run complex ETL jobs implemented in Amazon Redshift RSQL scripts in the AWS Cloud without having to manage any infrastructure. To achieve this, you can use

The Epos Now team is currently building both the fast access layer and a centralized lakehouse architecture-based data platform on Amazon S3 and Amazon Redshift for advanced analytics use cases. Having
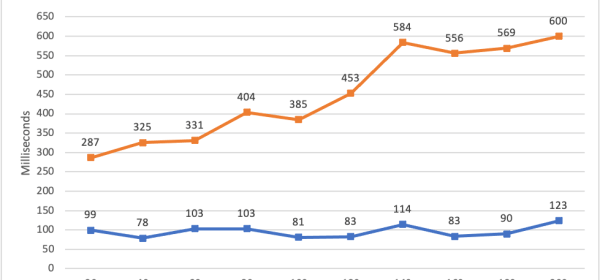
We’re excited to share dozens of new features to automate your schema conversion; preserve your investment in existing scripts, reports, and applications; accelerate query performance; and potentially simplify your

Amazon QuickSight is a fully-managed, cloud-native business intelligence (BI) service that makes it easy to connect to your data, create interactive dashboards, and share these with tens of thousands of users,

If not, we provide the following scripts in this post to help you launch a log aggregating system like Amazon OpenSearch Service or Splunk installed on an Amazon Elastic Compute Cloud (Amazon EC2) instance. A log

This post also demonstrates the capabilities of running queries against external databases, such as Amazon Redshift and PostgresSQL using Trino connectors, while controlling access at the database, table, row,

Data from the Data Lake Storage validated zone, transformed and enriched with more rules into its final processed state, loads to a dedicated SQL pool for running large scale analytical queries. Event

With several different options available, let’s cover five compelling reasons why Apache Iceberg is the table format to choose if you’re pursuing a data architecture where open source and open standards are

Plugsurfing uses Amazon OpenSearch Service as a central data store to store 300,000 charging stations’ information and to power search and filter requests coming from mobile, web, and connected car dashboard
In this second post of a multi-part series, we share best practices for choosing the optimal Amazon Redshift cluster, data architecture, converting stored procedures, compatible functions and queries widely
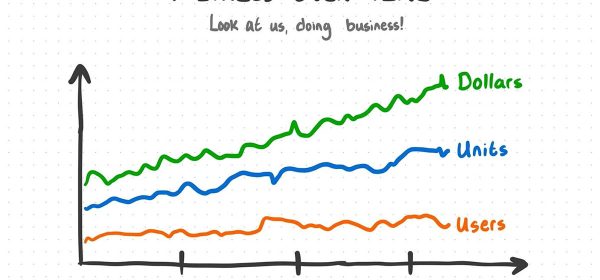
Structured Streaming leverages Delta Lake’s ability to track changes in your data to determine what data is part of an update and re-computes only the parts of your analysis that are affected by the new data. Without
Amazon Redshift has improved the performance of the classic resize feature and increased the flexibility of the cluster snapshot restore operation. Currently, in order to modify encryption on an Amazon Redshift