

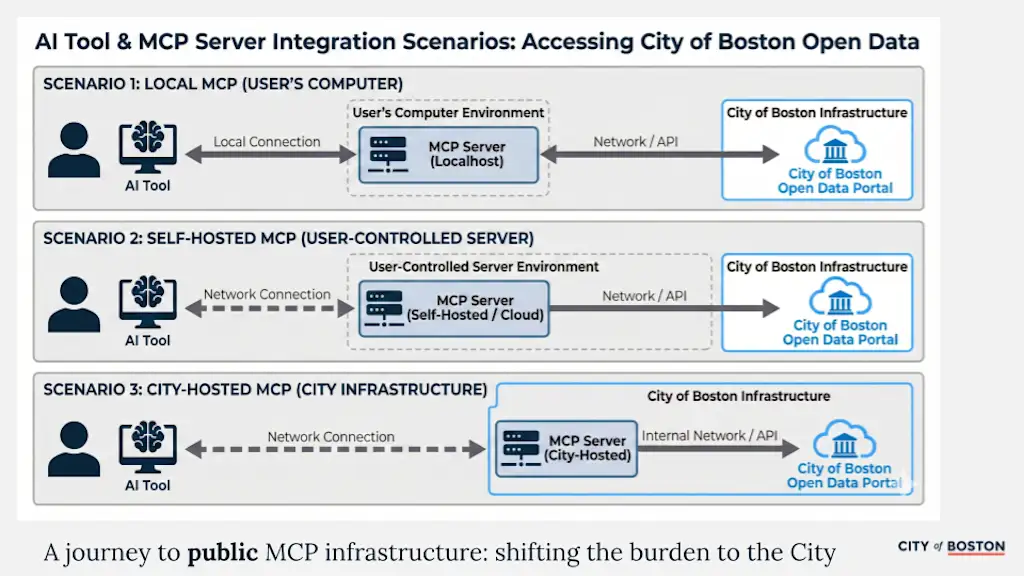
The architectural shift here is not “AI in government” so much as a new integration boundary. MCP acts like a control plane between models and public systems, which means cities can stop treating every AI tool as a bespoke one-off integration. For architects, the real value is standardization: a governed way to expose datasets, service workflows, and future transactional APIs without letting each model scrape or improvise its own path.
That middle layer also changes the security model. Once agent traffic becomes a first-class workload, cities need to think about authentication, authorization, logging, rate controls, and abuse detection for machine callers, not just people in browsers. The article’s open-data example is low risk, but the same pattern would become much more sensitive as it moves toward service requests, identity-linked interactions, or anything with eligibility, scarcity, or civil-liberties impact.
Operationally, the important trade-off is between reliability and flexibility. Pushing computation into the portal improves grounded answers and reduces dependence on model guessing, but it also means the underlying data platform must be queryable, well-described, and resilient under new usage patterns. In practice, success depends on metadata quality, API hygiene, and clear service boundaries more than on the model layer itself. Cities considering similar deployments should treat MCP as infrastructure work: it is closer to platform engineering and digital governance than to chatbot rollout.
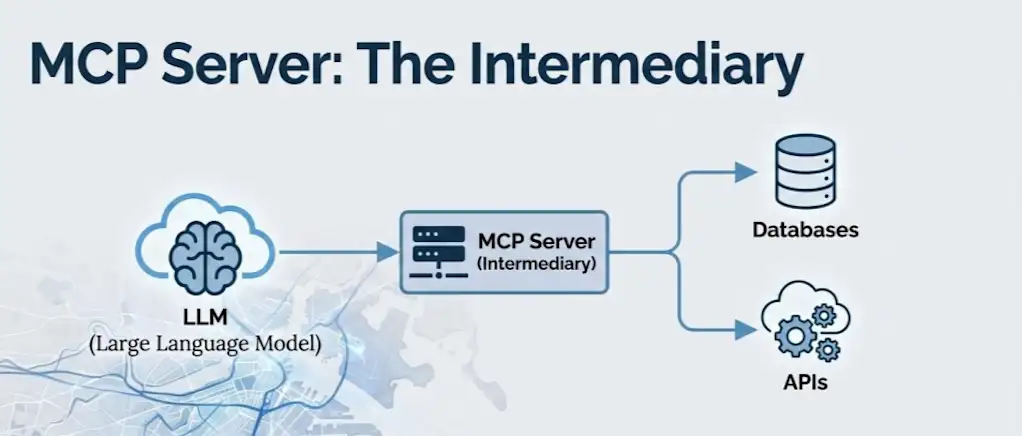 This is exciting for Boston because the world is moving fast, and we’re already seeing websites and services being activated or consumed by agents. MCP servers can serve as a layer through which the government can add governance and control.
Mechanically, an MCP server creates a set of tools. You describe, in plain language, when a tool should be used. Then you define what inputs need to be extracted from a natural-language request and how that translates into deterministic programmatic access to a resource. LLMs can be random; MCP is part of the pathway to make certain interactions more reliable and secure.
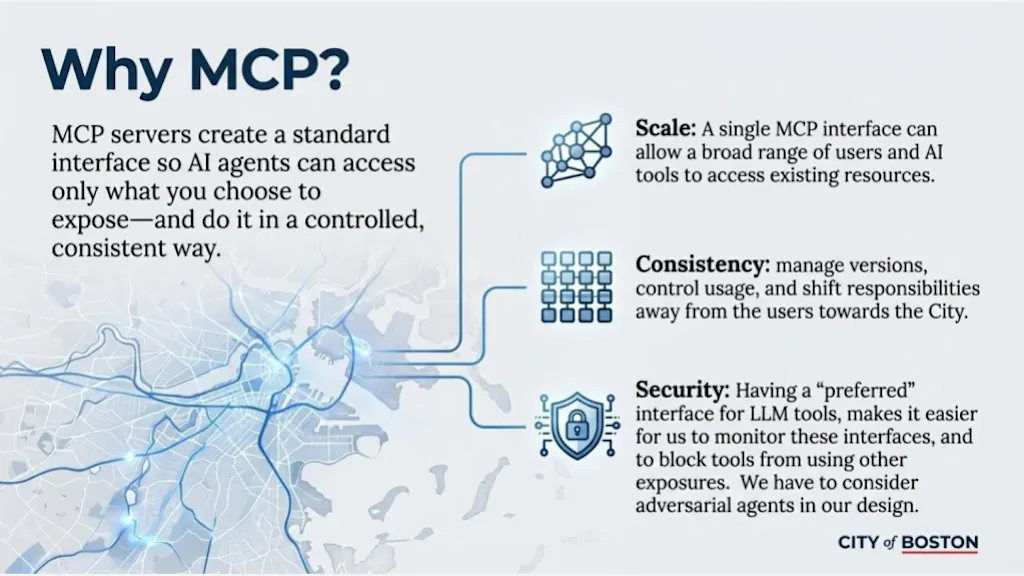
The dream is that cities invest in this infrastructure and point to different models to interact with a city’s MCP layer, ensuring it’s reliable, secure, and provides a better experience for people using agentic systems to interact with the government. A lot has to be true for that future, but we’re very excited about it.
 What normally breaks when people rely on “just the chatbot” and prompting, what problem is MCP solving?
Take our first MCP server: open data. If you ask Claude or ChatGPT or Gemini something like, “How many restaurants are there in Boston,” those models will answer using either (1) their training data, which is probably out of date, or (2) they’ll make something up. The risk of inaccuracy or hallucination is high.
It might do better if it can browse the web, but then you’re relying on it to find the right source, and we know a lot of information online is outdated or inaccurate. It might pull from an old report or an article from five years ago.
What we’ve been able to do with Open Context, our first MCP instance tied to Boston’s open data portal, is create a direct link between the portal and these AI tools. MCP servers are interoperable, so it doesn’t matter which AI tool you’re using.
If you ask an AI tool connected to this MCP server, “How many restaurants are there in Boston given the open data portal,” it automatically searches Boston’s portal, finds the right dataset, and generates a SQL query against that dataset. It queries live data reliably and returns an answer grounded in the city’s actual data infrastructure.
We spend a lot of money and time building data infrastructure that many people don’t use because it’s inconvenient. Most people don’t know SQL, and even knowing which dataset is right is hard. These tools bridge that gap, getting you to the right answer while avoiding many of the pitfalls in AI tools today.
 How did you make this more trustworthy and what did the development process look like?
We started in the fall of 2025 with students from Northeastern’s AI for Impact program at the Burnes Center. We’ve been rolling out a tool to Boston city employees called AI Launchpad, which provides access to LLMs, but we wanted it to be more useful.
We looked at how employees use AI tools, drawing on our experience and survey data. Data analysis is a common use case. But to analyze, people have to download data, paste it into a context, and go through a lot of steps. So our starting motivation was: how do we make those workflows easier, more convenient, and more reliable?
Around that time, I was at an AI retreat in Boston and spoke with Romesh Raskar at MIT about what the agentic web will look like and the need to build an open version of it. That weekend turned into action quickly. Saturday at the retreat, then Sunday speaking at MIT, challenging people to build better agentic experiences for Boston. Then, on Monday, we said, let’s try to build an MCP server and connect it to AI Launchpad.
Because we had brilliant students, by October, we had a prototype that connected to the open data portal. Since November and December, we’ve been iterating to make it more reliable. It did a good job finding datasets, but it wasn’t as strong at analyzing large datasets—good for small samples, less good at scale.
One innovation was to push more computation into the open data portal itself. Most data portals can run queries. So we’re using the portal to do more of the analytical work, which improves reliability and also makes the overall interaction more efficient and cost-effective.
 You’ve also talked about this as a replicable layer of digital public infrastructure. What else do cities need to be able to implement this?
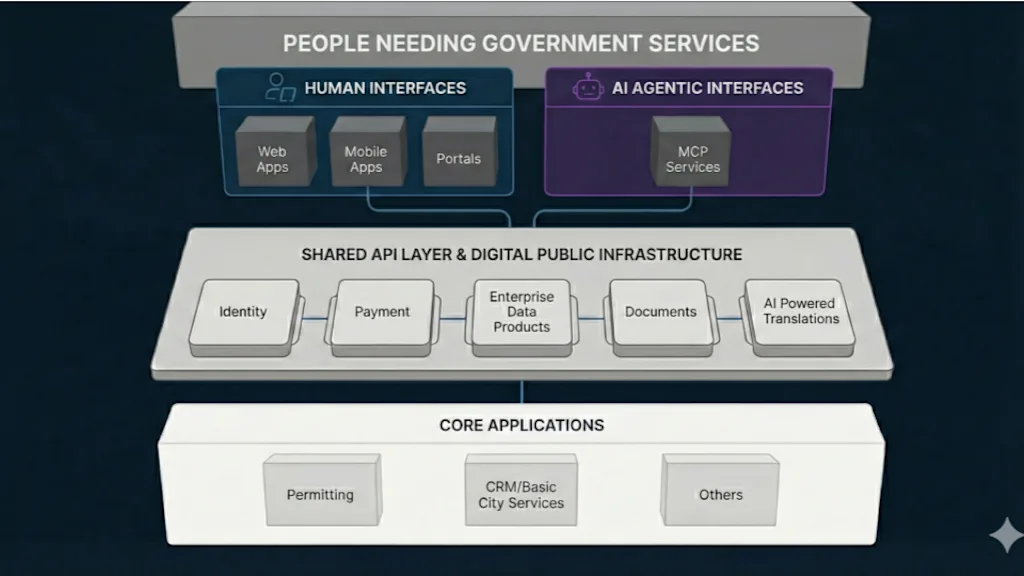
This is why we’re excited. With emerging technology, it’s possible we’ll be using a different acronym in six months, but right now, MCP looks like a real path to solve this. We think MCP is a component of digital public infrastructure and should be tied to digital public infrastructure (DPI). The agentic web is only helpful if it creates reliable, secure intermediation that serves real human beings. AI could help if someone is busy, doesn’t speak English, or has a disability. There are many reasons this could matter for access. But without the right infrastructure, the experience becomes less reliable.
The MCP pattern is appealing because it lets you leverage existing DPI components—identity, API exposures, payment APIs—by creating a middle layer between what an AI system “sees” and the underlying infrastructure the government already has, in a way that can be made more reliable.
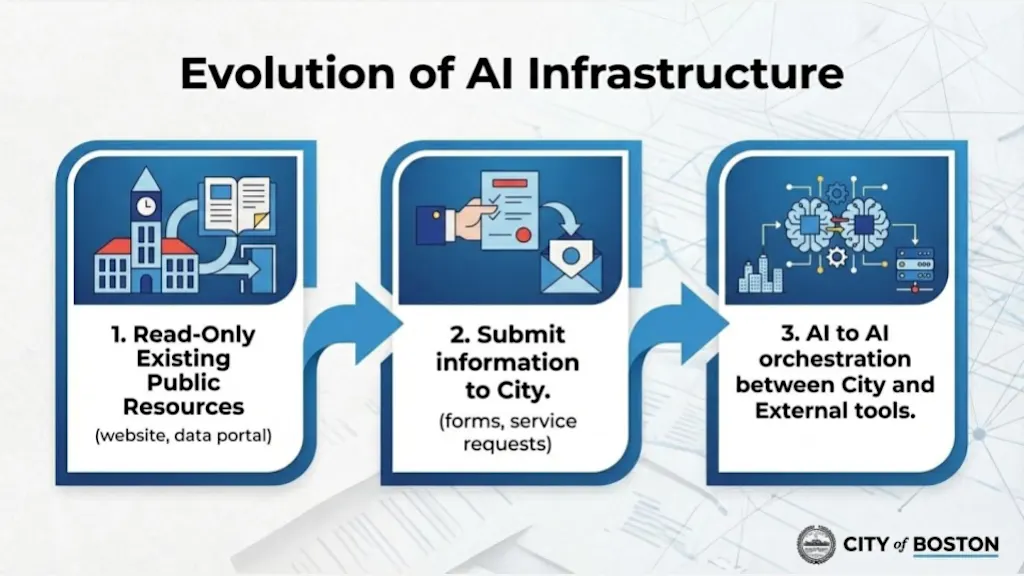
We’re starting with open data because it’s low risk and already public. But it could evolve to intermediation around service requests and other interactions. We believe the government should have the capability to build and steward this. But we can also imagine vendors incorporating this type of interface into the products they sell to governments.
Let’s talk about security. What threats feel most realistic with agentic systems, and how does MCP help?
One concern is that our APIs are not always well secured. There are agentic browsers and tools that make it easy to automate interactions. And we’re seeing more and more traffic to boston.gov that isn’t from people, it’s from AI systems scraping and “deep searching.”
It’s not hard to imagine AI tools also requesting services. A major risk is when an AI tool makes requests that aren’t tied to a real human need. You could have fraudulent requests or actors generating scarcity by consuming limited government resources and potentially reselling access, similar to ticket scalpers at concerts. Another risk is that without a controlled layer, it’s harder to secure and monitor the traffic between AI systems and government systems.
What excites us about MCP servers is that this middleware could make it easier to block unauthorized inbound agentic requests with cybersecurity tools, while still enabling legitimate uses. The idea is: people who need services use an authorized channel that the government controls, can associate with identity, and can monitor and secure end-to-end.
Without that middleware, government faces an uncomfortable choice: block agentic interaction entirely, or leave it open in the wild. MCP offers a middle ground: governance for agentic interactions.
 Are there things you’re intentionally not exposing MCP to right now?
We’re starting with open data. Our AI policies in Boston, rolled out a couple of months ago, state that we’re not using AI to process information that could affect people’s lives, property, or civil liberties because of reliability issues and intrinsic, complex biases. So, for now, those are categories we avoid. It’s not just “a human in the loop.” We know AI intermediation can create adverse effects that are hard to detect and remediate.
At the same time, we work closely with the disability community and with people who face language access issues. Government is hard to access for people who need it most. And those are often the same people least likely to have private access to LLMs, paid subscriptions, reliable internet, and personal devices.
If you had a magic wand, what’s the biggest blocker you’d remove?
There are technical gaps because MCP is new. Early on, MCP servers didn’t support some authentication pieces natively; we had to add frameworks to secure them. The ecosystem is changing fast.
But the biggest thing is discoverability and ease of use. We need to get to a point where using MCP infrastructure is as easy as pointing an LLM to a URL. With websites, you type the name or use search. We need that for MCP: trivial discovery, trivial access, effectively zero barrier to entry. We’ve made it easier, but there’s still too much technical legwork.
 For another city that wants to move in this direction, what actions should they take now?
Good metadata management is essential. LLMs consume data, but they don’t understand what it is without good descriptions and context. So it starts with good data governance.
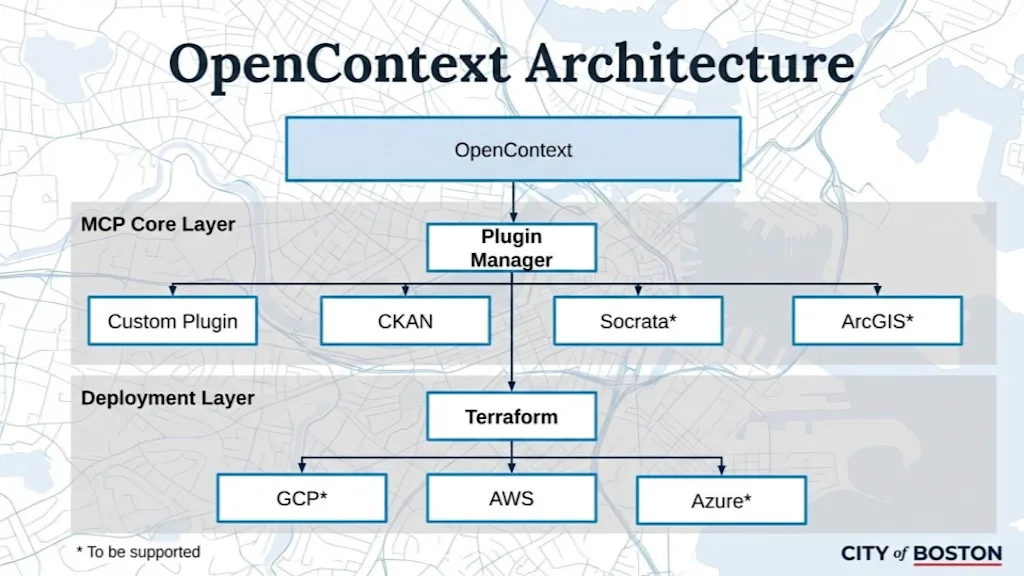
We intend to share this work. We’re proud of it, and it’s thanks to collaboration with the GovLab and the Burnes Center that we’ve been able to move quickly. We intend to make Open Context an open-source project so others can replicate it. The MCP server itself doesn’t cost a lot to run. Our goal is to make it as simple as deploying a package into whatever public cloud a city uses. The rest of the puzzle, how this ties into broader services, is something every city will have to solve, and we’re solving it in Boston, too.
But importantly, data becomes useful only when people use it. Data quality improved when we started publishing open data. We think governance and quality will improve further when more people use open data. And we’re hoping GenAI makes it easier for people to use open data, so we can solve problems collectively.
—
A version of this interview was also published at Reboot Democracy.
Enjoyed this article? Sign up for our newsletter to receive regular insights and stay connected.