
The architectural shift here is less about Redshift as a database and more about compute topology. By splitting a shared warehouse into a producer-consumer model, Vanguard turned one cluster into a managed data service with distinct execution planes. For IT teams, the practical lesson is that separate compute is often the cleanest way to protect ETL, BI, and exploratory analytics from each other’s failure modes.
The key dependency is Redshift data sharing, which lets consumers query live producer data without copying it into multiple warehouses. That simplifies synchronization, but it also changes how teams think about ownership, permissions, and workload isolation. Security boundaries, schema governance, and change management become more important because shared data products can be consumed by multiple groups with different latency and concurrency needs.
Operationally, the biggest win comes from replacing contention with specialization. Reserved, predictable capacity fits steady ETL, while serverless endpoints absorb bursty analyst and dashboard traffic. This is a useful pattern when teams have mixed workloads and no longer want a single sizing decision to define the service level for everyone. It also reduces the need for manual prioritization and makes performance behavior easier to reason about during incidents.
The next step toward data mesh adds a different challenge: shifting from platform-centric scaling to domain-centric ownership. That usually improves autonomy, but it also introduces more pipeline contracts, more stewardship responsibilities, and more opportunities for drift unless data quality, lineage, and SLAs are enforced consistently. In other words, the architecture scales because the operating model scales with it.
Business use cases and initial architecture
The scale and complexity of FAS operations generate enormous amounts of data that require sophisticated analytics capabilities to drive business insights, regulatory compliance, and operational efficiency. To address this, Vanguard launched the FAS 360 initiative. This initiative aims to empower Financial Advisor Services (FAS) with a centralized cloud data warehouse that integrates both internal and external data sources into a unified, intelligent system.Key business use cases:
- Business operations – Enables sales goal setting, tracking, and compensation management to drive operational excellence. It delivers insights on product usage patterns across financial advisor clients.
- Data science – Powers customer segmentation models and call transcription analytics to drive strategic insights. It also supports marketing campaign preparation and customer insights for sales call preparation.
- Exploratory analytics – Enables ad-hoc leadership questions, what-if scenario analysis, and sales trend analysis for channel managers competitor comparative analysis.
Centralized data warehouse FAS 360:
Vanguard’s first wave of modernization established FAS 360 as a centralized enterprise data warehouse, migrating from a fragmented “data swamp” of Parquet files on Amazon Simple Storage Service (Amazon S3) to a structured, unified system. The following architecture diagram leverages Amazon S3 for raw data storage with Amazon Redshift serving as the core processing engine, providing integrated access for BI tools, analyst exploration, and data science workloads.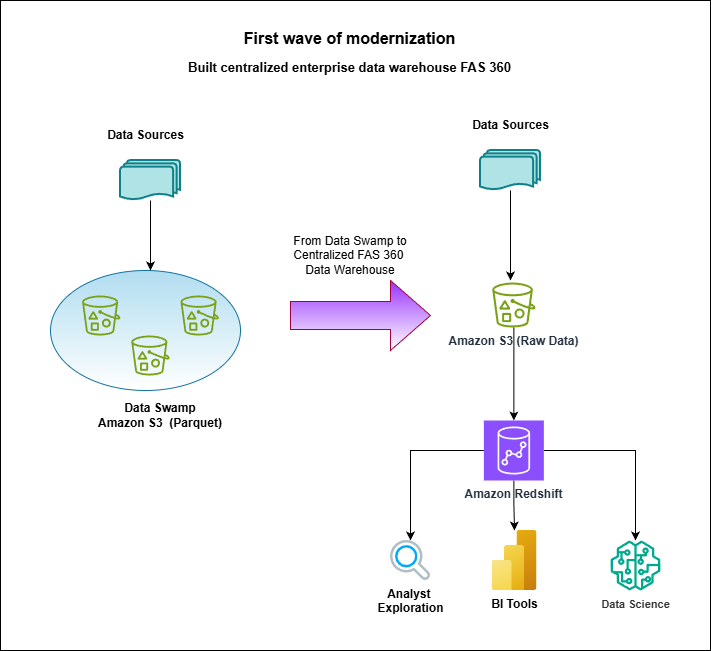 Here are the key benefits achieved with this architecture:
- Single source of truth – Consolidated fragmented data sources into a unified system, minimizing multiple versions of truth and establishing consistent reporting practices across the organization
- 10x faster query performance – Dramatically improved query response times compared to the previous solution, helping enhance analyst productivity and enabling more complex analytical workloads
- Seamless data lake integration – Maintained connectivity with the broader data lake environment while providing structured warehouse capabilities
- Enhanced business agility – Increased trust in metrics and unlocked new use cases that were previously untenable, directing the new migration efforts toward the FAS360 system
Significant growth and expanding use cases
Vanguard FAS experienced remarkable growth in their data analytics requirements over a two-year period, demonstrating the rapid evolution of modern data needs: Initial State:- 20 AWS Glue ETL jobs processing daily data loads
- Approximately 100 tables in their data warehouse
- 20 Tableau dashboards serving business users
- Around 60 analysts accessing the system
- 20 TB in data volume in Amazon Redshift and another 150 TB in S3 data lake
- 600+ AWS Glue ETL jobs (a 30x increase) handling complex data transformations
- 300+ tables (3x growth) storing diverse business data
- 250+ Amazon Redshift materialized views optimizing query performance
- Over 500 Tableau dashboards (25x expansion) serving various business functions
- 500,000+ user queries/months
Resource contention and performance bottlenecks
As Vanguard FAS’s data environment expanded, their initial architecture, a single Amazon Redshift provisioned cluster with 2 nodes (ra3.4xlarge), began experiencing severe performance challenges that threatened business operations: ETL performance issues:- Frequent ETL SLA failures disrupting critical business processes
- Tableau extract failures resulting in stale dashboard data
- Resource conflicts between data ingestion and transformation workloads
- Poor query performance during peak usage periods
- Table and object locking issues preventing concurrent access
- Frustrated analysts unable to perform deep data exploration
- Limited ability to run long-running analytical queries
- Resource contention between ETL workloads and interactive analytics
- Inability to scale compute resources independently for different workload types
- Single point of failure affecting the data operations
- Difficulty in workload prioritization and resource allocation
Solution overview
To address these critical challenges, Vanguard FAS implemented following multi-warehouse architecture that leverages the advanced data sharing capabilities of Amazon Redshift for workload isolation and independent scaling.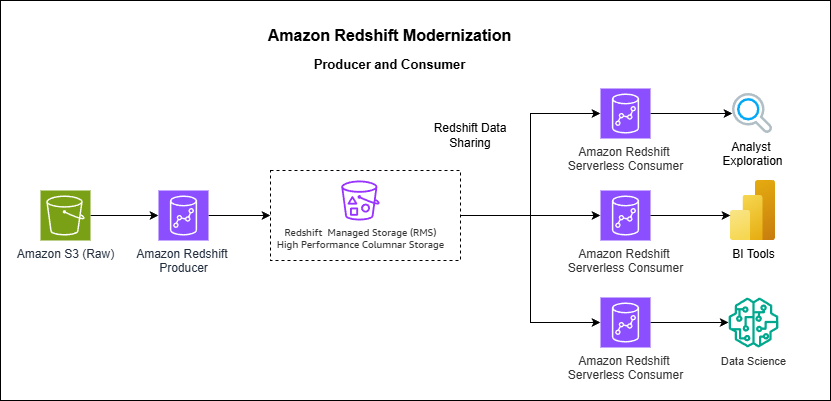 Producer – Amazon Redshift Provisioned Cluster
The central hub consists of the original Amazon Redshift provisioned cluster with RA3 nodes, optimized for consistent, predictable workloads:
- Dedicated ETL processing: Handles data ingestion, transformation, and loading operations
- Write workload optimization: Manages data writes and updates without interference
- Cost optimization: Utilizes reserved instances for predictable, steady-state workloads
- Data governance: Serves as the single source of truth for the enterprise data
- Analyst Exploration: Dedicated environment for analyst data discovery and experimentation
- BI Tools: Instance optimized specifically for Tableau dashboard and visualization workloads
- Data Science: For complex and long running machine learning workloads in completely isolated environment
Results
The implementation of the multi-warehouse architecture delivered significant improvements across the key performance indicators:Predictable Performance
Nightly ETL cycles now consistently complete before the 9 AM SLA, eliminating the previous SLA failures that disrupted business operations and ensuring fresh data is available for morning business activities. Dashboards and reports now reflect the most current data available, providing teams with up-to-date insights for decision-making.Improved Analyst Productivity and Experience
The new architecture removed the restrictive 10-minute query timeout that previously prevented deep ad hoc exploratory queries. Analysts can now run complex analytical workloads exceeding 30 minutes in a fully isolated environment without impacting other users or ETL processes. This change, combined with significantly faster query response times, has led to higher analyst satisfaction and productivity across the team.New Analytical Capabilities
The architecture introduced a dedicated “Data Lab” environment where analysts have write access to experiment with data usingCREATE TABLE AS SELECT (CTAS) commands. Each workload type can now scale independently based on demand, with different consumer clusters optimized for specific use cases, enabling more sophisticated analytical approaches.
Operational Excellence
The separation of workloads enabled efficient utilization of compute resources across different patterns, leading to better cost control through appropriate sizing, serverless pay-as-you-go pricing, and reserved instance usage. The cleaner separation of concerns between ETL and analytics workloads has simplified overall management of the data platform.Ongoing modernization: Evolution toward data mesh architecture
As Vanguard’s data environment matured and their success with the multi-warehouse architecture enabled broader adoption across the organization, they recognized an opportunity to evolve their architecture to match their organizational growth. The expanding portfolio of data products and increasing number of teams leveraging the system created new opportunities for innovation. As Vanguard’s data environment grew, three key challenges emerged:- Centralized ownership bottleneck – Single-team data ownership couldn’t scale with the growing number of data products
- Write workload contention – Resource contention persisted for write operations on shared endpoints
- Cross-domain dependencies – Data object interdependencies across business domains slowed data product development
Rationale for Data Mesh
Vanguard’s decision to adopt Data Mesh was driven by the need to:- Decentralize data ownership by establishing data domains with dedicated stewards
- Remove write contention by isolating each domain’s data loads to separate endpoints
- Enable autonomous development allowing stewards to own the complete data product lifecycle and governance
- Leverage modern data lake capabilities using AWS Glue and Apache Iceberg format for data product curation
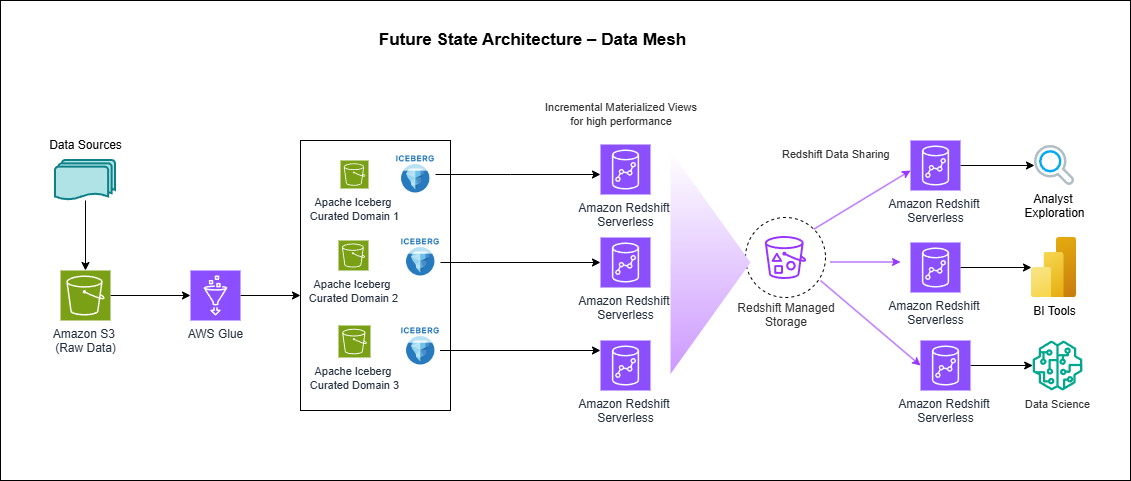 This new data mesh architecture has several key components that work together to enable scalable, domain-oriented data management.
Domain-Oriented Data Ownership
Vanguard is establishing distinct data domains aligned with business functions and assigning dedicated data stewards to each domain for clear ownership and accountability. This strategy shifts from centralized data management to a decentralized model where data ownership and responsibility can be distributed across business domains, enabling teams closer to the data to make informed decisions about their domain-specific needs.Distributed Data Architecture
The new architecture isolates domain-specific data loads to separate compute endpoints and creates independent data processing pipelines for each domain. This approach helps reduce cross-domain dependencies and conflicts that previously slowed development cycles, allowing teams to iterate and deploy changes without waiting for coordination across the entire organization.Data Product Approach
Vanguard is curating data products on the data lake using Apache Iceberg format and leveraging AWS Glue for metrics computation and data lake integration. This approach treats data as products with defined SLAs and quality metrics, helping facilitate reliable, high-quality data delivery that downstream consumers can depend on with confidence.Self-Service Analytics
The implementation enables domain teams to manage their complete data product lifecycle independently while maintaining enterprise governance standards. Vanguard provides comprehensive tools and systems for independent data management, allowing teams to innovate quickly without compromising data quality or security, ultimately accelerating time-to-insight across the organization.This evolution represents a natural progression from centralized data warehouse to multi-warehouse architecture, and finally to a fully distributed, domain-oriented data mesh that can scale with Vanguard’s continued growth.Conclusion
Vanguard Financial Advisor Services’ journey demonstrates that scaling analytics is no longer about scaling a single warehouse bigger, but about architecting for workload isolation, independent scaling, and organizational growth. By evolving from a single 2-node RA3 provisioned cluster to a multi-warehouse architecture using Amazon Redshift Serverless and Provisioned, Vanguard achieved measurable, production-grade outcomes:- 500,000+ monthly queries supported without ETL or dashboard contention
- 100% ETL SLA adherence, with nightly pipelines completing before 9 AM
- 25x growth in BI consumption (20 → 500+ Tableau dashboards) without performance degradation
- 8x growth in analyst population (60 → 500+) enabled through workload isolation
- 30x increase in ETL pipelines (20 → 600+) without re-architecting ingestion logic
- Zero-copy Amazon Redshift data sharing across producer and consumer warehouses, minimizing data duplication and synchronization costs
- Removal of 10-minute query limits, unlocking advanced exploratory and long-running analytics
About the authors
Alex Rabinovich
Alex is a Director of Data Engineering at Vanguard, aligned to Financial Advisory Services division. In this role, he leads large‑scale data engineering platforms and modernization initiatives, focusing on building reliable, scalable, and high‑performance data systems in the AWS cloud.Anindya Dasgupta
Anindya is a solutions architect in Vanguard’s Financial Advisor Services Technology division. He has over 25 years of experience building enterprise technology solutions to address complex business challenges. His work focuses on architecting and designing scalable, cloud‑native and data‑driven systems, with hands‑on contributions across application development, system integration, and proof‑of‑concept initiatives.Vijesh Chandran
Vijesh is Head of Solution Design, overseeing the architecture and design of enterprise technology solutions that support critical business outcomes. His background spans data architecture on cloud‑native platforms, and data‑driven systems, with a strong focus on aligning technology design to business strategy. He plays a hands‑on role in guiding solution direction, integration patterns, and proof‑of‑concept initiatives.Raks Khare
Raks is a Senior Analytics Specialist Solutions Architect at AWS based out of Pennsylvania. He helps customers across varying industries and regions architect data analytics solutions at scale on the AWS platform. Outside of work, he likes exploring new travel and food destinations and spending quality time with his family.Poulomi Dasgupta
Original Postoulomi-dasgupta-52568954/" target="_blank" rel="noopener" shape="rect">Poulomi is a Senior Analytics Solutions Architect with AWS. She is passionate about helping customers build cloud-based analytics solutions to solve their business problems. Outside of work, she likes travelling and spending time with her family.Enjoyed this article? Sign up for our newsletter to receive regular insights and stay connected.