
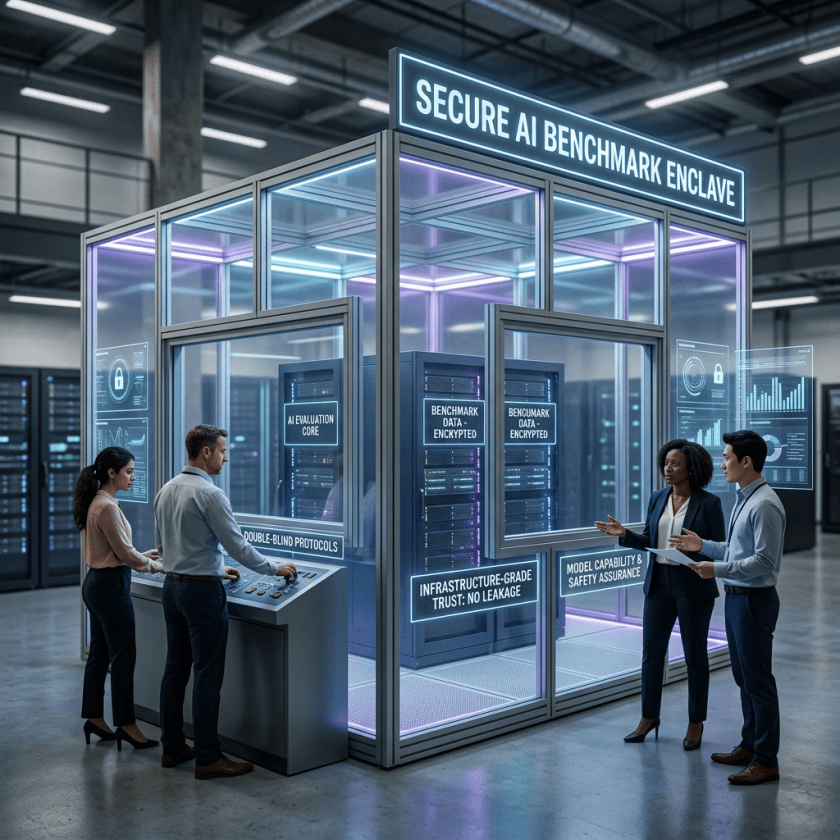
The technical significance here is not just better benchmarking hygiene; it is the emergence of evaluation infrastructure as a security boundary. For enterprises that depend on third-party model claims, a double-blind process backed by confidential computing changes the trust model from “believe the benchmark owner” to “verify the isolation mechanism.” That distinction matters because benchmark contamination is increasingly an operational risk, not merely a research nuisance: it can distort model selection, inflate safety confidence and mislead downstream deployment decisions.
The implementation questions are where this becomes practically interesting. A cryptographic evaluation “box” is only as credible as its attestation chain, prompt-handling controls, output retention rules and separation between evaluation workloads and later training or tuning pipelines. Teams assessing similar approaches should ask whether prompts, model responses, telemetry and intermediate artifacts remain inaccessible outside the secure enclave, and how independent parties can verify that claim without exposing the benchmark itself.
Architecturally, this points toward a new layer in AI governance stacks: protected evaluation environments that sit between model providers and external assessors. Over time, these could become as important as CI/CD controls or data-loss-prevention policies for organizations shipping high-stakes AI. The likely trade-off is complexity. Secure enclaves, attestation workflows and tightly controlled partner access improve integrity, but they also raise integration, cost and reproducibility questions. Practitioners should watch whether these methods can scale beyond flagship evaluations into repeatable pipelines for procurement, model validation and regulated assurance.
Building trust in proprietary model benchmarks using cryptographically secure environments
Imagine a student is set to take a high-stakes exam. If they accidentally peek at the test questions in advance, achieving a perfect score is influenced by this knowledge, making it a meaningless accomplishment. To truly measure what they know, they must have no visibility of the test questions until it’s time to take the exam. That is the exact challenge the industry faces when evaluating advanced AI models. If a model has already seen the test questions – a problem known as benchmark contamination – the results can only be trusted to an extent.
Today, we’re introducing the world’s first double-blind evaluation of a proprietary, frontier class AI model, which keeps external evaluations confined to a cryptographic “box” where they can’t be used by models later to optimize performance ahead of testing. We’re partnering with the Singapore AI Safety Institute, OpenMined, AVERI, and MLCommons, to test a Gemini Flash Lite model against confidential benchmarks in a privacy-preserving environment, increasing evaluation integrity.
At Google, we assess our AI systems using a broad spectrum of evaluations throughout model development and deployment, but we don’t rely on internal testing alone. To identify potential blindspots, we work with a diverse group of external partners, including specialized research labs, civil society and national AI Safety and Security Institutes (AISIs), using their unique expertise to stress-test our models.
As AI models become more capable, ensuring the model has not seen the test questions or prompts in advance is critical, as this can skew the results. Policymakers, researchers, and enterprises need to trust that AI benchmarks accurately reflect a model’s true capabilities and safety, but if models are able to “peek” at the evaluation questions in advance, it can artificially inflate scores and undermine this trust.
Although zero-logging protocols and rigorous contractual safeguards have long kept external test prompts confidential, incorporating technical and cryptographic safeguards marks a major step forward in secure model evaluation.
How double-blind evaluations work
Enjoyed this article? Sign up for our newsletter to receive regular insights and stay connected.