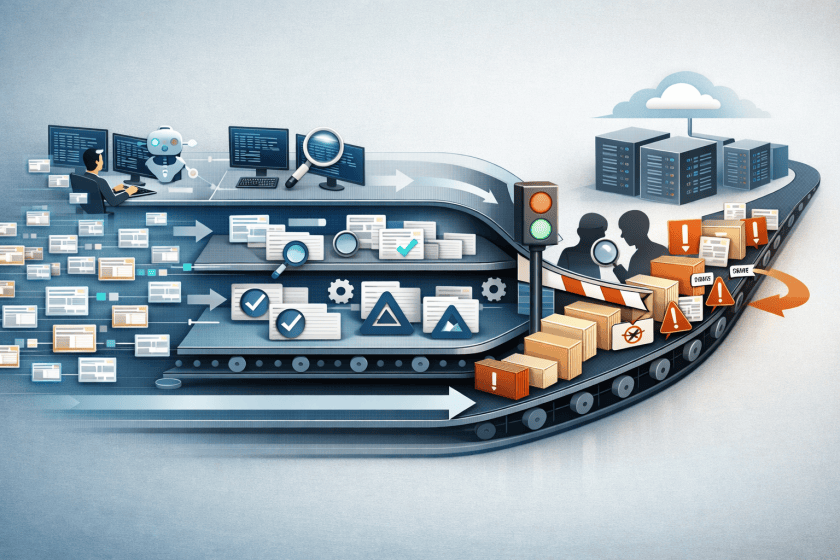
For platform and DevOps teams, this becomes a pipeline design problem. If AI-assisted commits are rising, release governance has to become more explicit about what constitutes sufficient proof: static analysis, dependency risk, test impact analysis, coverage deltas, rollback readiness and traceability from prompt or assistant usage through commit and deployment. Without that evidence trail, incident response will struggle to distinguish a model-induced defect from an ordinary engineering error, which matters for remediation, compliance and future guardrails.
There is also an architectural trade-off hidden underneath the productivity gains. Systems with weak modularity, sparse observability and broad blast radius make AI-generated changes disproportionately expensive to verify. In those environments, every faster commit multiplies uncertainty. Teams will get more value from improving service boundaries, testability and release isolation than from adding yet another code-review assistant.
What practitioners should examine next:
- whether review queues are growing faster than commit volume,
- which classes of change can be auto-approved versus manually gated,
- how quickly an incident can be traced to code origin, dependencies and deployment context,
- whether architecture reduces the cost of verification or silently inflates it.
Something specific happened to software delivery in the past two years. The 2026 survey data is unusually clear about what it was.
Sonar’s 2026 State of Code Developer Survey found that AI-generated or AI-assisted code accounted for 42% of code committed by respondents, with developers projecting that share to reach 65% by 2027. GitLab’s 2026 AI Accountability Report, a Harris Poll survey of 1,528 developers and technology buyers across six countries, found that 85% agree AI has moved the bottleneck from writing code to reviewing and validating it.
Both figures get quoted often. The part that gets left out is that the bottleneck didn’t wander downstream on its own. Engineering organizations moved it there.
The Half That Got Automated Was Already Cheap
PractiTest’s 2026 State of Testing Report puts AI adoption across testing organizations at 76.8%. Where that adoption went is the more useful number. Teams use AI for test case creation at 69.6% and for script maintenance at 59.6%. Risk identification sits at 19.9%.
Writing test cases was tedious and consumed real hours. It was almost never the thing that gated a release.
What gates a release is deciding what is worth testing: how much a given change can break, whether existing coverage maps to the risk the team actually carries, which of fifty findings matters before Thursday. That work is judgment. It doesn’t get faster when the typing gets faster, and it’s sitting at 19.9%.
The part of quality that a patient person could grind through got fast. The part that requires someone to think was left alone, while the volume flowing into it surged.
Almost Nobody Fully Trusts the Code, but Verification Still Lags
Sonar’s survey of more than 1,100 developers also found that 96% do not fully trust AI-generated code. It also found that 48% always verify it before committing.
Nearly everyone reports some distrust of AI-generated code, while fewer than half say they always verify it before committing.
The underlying economics are worse than they look. In the same survey, 38% said reviewing AI-generated code takes more effort than reviewing code a colleague wrote. There may be no human author to go ask in the traditional sense. It also lands in bigger batches than a person would have produced. The volume needing review climbs toward 65% of everything committed while the cost of each review goes up. That part is arithmetic.
The Confidence Gap Is Bigger Than the Capability Gap
GitLab’s report found that 87% of respondents are confident they could identify whether AI-generated code was involved in an incident within 24 hours. Among organizations that had actually had such an incident, 34% couldn’t make that call. The same survey found that 43% can’t reliably tell AI-generated code from human-written code at all.
Perforce’s 2026 State of DevOps Report, based on more than 800 IT professionals, gets there from a different angle—77% express confidence in their AI outputs. Only 38% have AI embedded across multiple delivery stages, and only 39% maintain fully automated audit trails.
The real divide is not between teams that can trace AI-generated code and teams that cannot. It is between teams that know which one they are and teams that find out during a postmortem.
Tooling Cannot Close a Judgment Gap
The common reflex is another tool: a platform that reviews the AI-generated code.
Some of that works, and those tools are improving. But someone still has to decide what the tool blocks, and what false positive rate a team will tolerate before they start ignoring it entirely. Someone has to decide what happens when it flags a change the day before a release. Those are judgment calls, and no tool makes them for a team.
Original Postress-releases/world-quality-report-2025-ai-adoption-surges-in-quality-engineering-but-enterprise-level-scaling-remains-elusive/" shape="rect">The World Quality Report 2025-26 points to the same broader problem after 17 editions: Generative AI adoption in quality engineering is growing rapidly, but enterprise-level scaling remains limited. The report found that only 15% of organizations have scaled generative AI in quality engineering enterprise-wide, compared with 43% still experimenting.
Verification capacity is a staffing decision before it’s a tooling one. Teams crossing this line often find the answer is a dedicated DevOps engineer who owns the pipeline and the gates. One more subscription won’t decide what those gates should mean.
What to Measure Instead
Deployment frequency is going to look excellent. It measures the half that got cheaper.
A more honest signal is rework: how much cleanup follows a release relative to the size of that release. A release carrying one change points directly at what broke, and a release carrying forty points at nothing. When AI raises throughput while review capacity stays flat, that ratio moves first.
The second measurement is GitLab’s question, run as an exercise rather than a survey. Take a recent incident and time how long it takes someone to establish whether AI-generated code was involved. Asking a team whether they could is a much easier question to pass.
The Bottom Line
Generation got cheap in about two years. Verification didn’t, because verification is mostly a person deciding what matters. Nobody has automated that away yet. The organizations that handle the next two years well will be the ones that staffed for the half that stayed expensive.
Enjoyed this article? Sign up for our newsletter to receive regular insights and stay connected.