
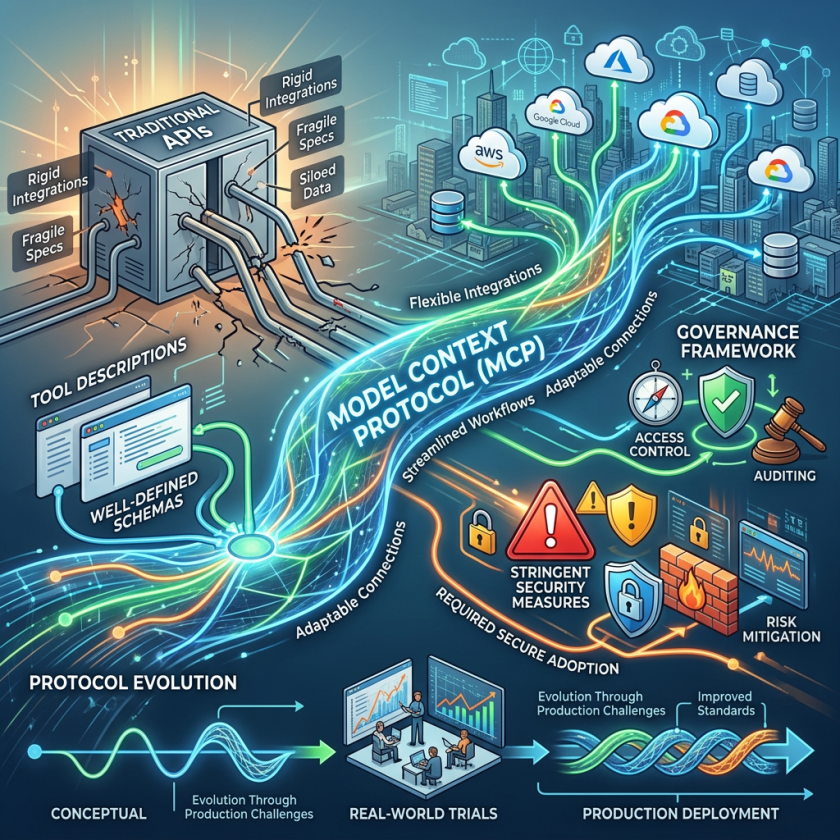
MCP shifts integration work upward in the stack, but that also changes where operational risk lives. Once the client is no longer a single app framework but a model making runtime decisions, the real engineering burden moves into tool design, governance, and failure containment. That means API review alone is not enough: teams need to validate descriptions, schemas, and adjacent-tool boundaries with the same discipline they apply to public interfaces, because the model will infer intent from whatever is written there.
The architectural trade-off is flexibility versus predictability. MCP’s shared primitives reduce duplicated adapters, but the runtime composition it enables makes call order, branching, and fallback behavior emergent rather than programmed. For enterprise teams, that has direct implications for observability and test strategy. You need logs that reconstruct tool chains end to end, plus harnesses that exercise multi-tool paths, not just individual calls. Otherwise, the first failure may appear only when a particular sequence crosses system boundaries in production.
The protocol’s recent evolution also points to deployment constraints that matter in real fleets. Stateless operation, formal tasks, and hardened authorization are not cosmetic additions; they address scaling, long-running workflows, and privilege control. That suggests any serious rollout should start with allowlisted tools, explicit auth on every endpoint, and immutable audit trails. Teams that treat MCP as a convenience layer risk importing technical debt in the form of unsafe defaults, while teams that treat it as a governed integration fabric can gain reuse without giving up control.
Ask most engineers what MCP is and you’ll get the same answer: a way to plug tools into an LLM. Fair enough, as far as it goes. But that description treats MCP like plumbing, and after months building MCP-based integrations for large enterprise platforms, I don’t think plumbing is the right metaphor. Plumbing moves water through pipes you already designed. MCP changes who’s holding the wrench. Once you’ve felt that shift in a real production system, the “just another API standard” framing stops making sense.
This piece is the long version of that argument. It walks through what MCP’s primitives actually are and why they’re the right primitives, where the standard genuinely collapses integration work that used to be duplicated per framework, where the abstraction leaks in ways that only show up once you’re past the demo, and what the protocol’s own 2026 evolution tells you about where the real pain has been. Nearly everything worth knowing about building on MCP falls out of understanding these pieces and how they interact.
What MCP actually standardizes
Strip away the framing and MCP is a JSON-RPC-based protocol that lets a client (the thing driving an LLM) talk to a server that exposes capabilities, over a small, fixed set of primitives:
Tools are callable functions. Each one has a name, a description, and a JSON Schema describing its inputs. This is the primitive most people mean when they say “MCP,” and it’s the one doing the heavy lifting in most production deployments: “look up an order,” “run a query,” “create a ticket,” etc.
Resources are readable context, addressed by URI, that a client can pull in without the model having to call a function to get it: a file, a record, or a document, for instance. Think of this as the read side of the interface, separate from the “do something” side that tools represent.
Prompts are reusable templates a server offers to the client, so common workflows don’t have to be respecified from scratch every time.
On top of those three, the spec defines capabilities that flow the other direction, from server back to client: Sampling lets a server ask the client’s model to generate text on its behalf; elicitation, added in the 2025-06-18 revision, lets a server pause and ask the human for more input mid-task; and roots let a server learn which directories or URIs it’s actually allowed to touch.
None of these primitives are individually novel. What’s novel is that they’re the same five primitives regardless of which model, which framework, or which vendor is on the client side. That’s the entire value proposition in one sentence, and it’s also the source of everything that goes right and everything that goes wrong when you build on top of it.
Where the old model breaks down
Before MCP, wiring an LLM into an enterprise system meant writing tool-calling code for that specific model, that specific framework, that specific integration. Every agent framework had its own function-calling convention: its own way of describing a schema, its own way of parsing a model’s intent to call something, and its own error-handling contract. Every system you wanted to expose needed its own adapter written to whichever dialect that framework spoke. Add a second framework to your stack and you don’t get twice the work. You get a second, incompatible copy of the same logic, maintained by whoever drew the short straw.
MCP replaces that with one contract, written once, usable by any compliant client regardless of which model sits behind it. That’s the part every MCP explainer gets right, and it’s a real, measurable win. I’ve watched it collapse from a maintenance burden that used to scale with the number of frameworks a team happened to be supporting that quarter down to something that scales with the number of systems, full stop.
But the more consequential change is where the integration decision gets made. A traditional API integration is an agreement two systems make in advance. You negotiate a contract: endpoints, payloads, auth, versioning, and both sides build to it, because a project plan said this integration should exist. The plan predates the code.
An MCP server doesn’t get that luxury. It has no idea which agent will call it, in what sequence, alongside which other servers, in service of what goal a human typed into a chat box 30 seconds ago. The plan doesn’t exist as a concrete thing until the agent composes one, at runtime, out of whatever tools happen to be available to it. That’s not a stylistic difference from the old model. It’s a different category of integration problem, because the party doing the composing isn’t your code anymore. It’s a model, reasoning over natural-language descriptions you wrote weeks or months earlier, with no idea what context it would eventually be reasoning inside of.
The description is the interface now
A tool’s JSON Schema tells the agent what parameters it takes and what shape they need to be. That part is mechanical, and MCP handles it well. The tool’s name and description tell the agent when to use it at all, and whether to prefer it over some other tool that does something adjacent. Those are two different jobs, and only one of them is solved by a well-formed schema.
Picture two versions of the same tool description. The first is technically correct and nothing more:
{
  "name": "get_status",
  "description": "Returns the current status of a record given its ID."
}
An agent reading that has no idea when this is the right tool versus three other tools that also return some kind of status, no idea what “record” means in this system, and no idea whether IDs are case-sensitive, numeric, or prefixed. The second version spells out the domain the tool operates in, gives the ID format explicitly, states what the returned status values mean, and flags the one adjacent tool this one is commonly confused with and why they’re different:
{
  "name": "get_status",
  "description": "Returns the current fulfillment status for an order record.
IDs are numeric order numbers (e.g. 48213), not SKUs or customer IDs. Status
values are one of: pending, processing, shipped, delivered, cancelled. Use this
instead of get_shipment_status, which returns carrier tracking events rather
than the order's internal state."
}
That’s a longer description, and it will feel like overexplaining to the engineer writing it, because the engineer already knows all of this. The agent doesn’t. It’s encountering the tool for the first time, with a handful of tokens to decide whether it’s the right call, and no colleague to ask.
I’ve watched teams ship a technically correct MCP server that agents used badly, or avoided entirely in favor of a worse but better-described alternative, purely because of this gap. The failure mode isn’t a stack trace. It’s an agent confidently calling the wrong tool, or the right tool with an assumption baked in that happened to be wrong for this case, and nobody notices until the output looks slightly off downstream. Writing tool descriptions well is closer to technical writing and product design than it is to backend engineering, and it’s not a skill most integration teams (mine included, early on) walked in the door with.
Composition is emergent, and that cuts both ways
The entire appeal of MCP is that an agent can combine tools from servers that never agreed to work together, in combinations their respective authors never planned for. That’s also the risk, and it’s structural, not a bug you fix with better testing.
In a traditional integration, the sequencing logic (call A, then check its result, then decide whether to call B or C) lives in a script that a human wrote and a reviewer read. You can unit test it. In an MCP-based agent, that same sequencing logic lives in the model’s runtime reasoning, generated fresh for each task based on the goal it was given and whatever tools happen to be available in that session. You can’t unit test a decision that doesn’t exist until the moment it’s made.
A tool that behaves correctly in isolation, with the exact inputs its author tested against, can still produce a bad outcome the first time an agent calls it third instead of first in a chain, or passes it a value that came from a different server’s output rather than a human’s direct input. This is qualitatively different from a normal integration bug, because it doesn’t show up in code review, and it won’t show up in testing unless your test suite happens to exercise that specific, unplanned chain of calls. It shows up in production, once, when a particular combination finally occurs. That’s exactly the kind of failure mode that’s cheap to dismiss as an edge case until it happens to the wrong customer.
The protocol is catching up to its own success, in specific and telling ways
To be fair to MCP, it isn’t standing still, and the shape of its evolution tells you a lot about where the real production pain has been. The July 28, 2026 specification is the largest revision since the protocol’s November 2024 launch, and every major change in it traces back to something that broke, or nearly broke, at scale.
The protocol core is now stateless. The original design tracked sessions with an MCP-Session-Id header, workable for a single server instance but painful the moment you’re running behind a normal horizontally scaled fleet and discover that “any instance can answer any request” and “sticky session state” don’t coexist. Removing protocol-level sessions means the same request can be served by any instance behind ordinary load-balancing infrastructure, which sounds unglamorous right up until you’re the one who has to explain in an incident review why a routine deploy dropped a chunk of in-flight sessions.
Tasks formalize long-running work. A lot of real enterprise work (document processing, multistep approvals, anything involving a human in the loop) doesn’t complete inside a single request/response cycle. Before this extension existed, teams hand-rolled this with polling loops and webhook callbacks, each implementation slightly different, each one a source of its own edge cases. Tasks turn that into a first-class protocol concept.
MCP Apps let a server return interactive UI, not just structured data. That matters the moment a “tool” is something a human needs to actually look at and approve before it fires, which in any environment with real consequences attached is often.
Authorization was hardened to align with OAuth 2.1 and OpenID Connect. This one isn’t novel so much as overdue, and the gap it closes was a real one; see the governance section below.
A formal deprecation policy now governs the legacy HTTP+SSE transport, with a 12-month offramp. That’s the kind of unglamorous governance maturity a protocol only earns after it’s been run in production long enough for someone to need it.
None of this is exciting reading. All of it is the sound of a two-year-old protocol absorbing genuine operational scar tissue, which is a far better signal about its trajectory than raw adoption numbers. And the adoption numbers are themselves striking: The official registry tracks close to 10,000 distinct servers, Tier 1 SDK downloads run into the tens of millions monthly, and both the TypeScript and Python SDKs have individually crossed a billion total downloads. Competitors of the protocol’s original author adopted it within months. That combination, real scale plus a spec that keeps changing in response to real production failure modes, is a much stronger signal of durability than either fact alone.
Governance hasn’t caught up
Here’s what I’d want any team to weigh before connecting MCP to anything that matters. Independent security research through 2026 paints a specific, and specifically uncomfortable, picture of the current ecosystem.
Scans across thousands of publicly registered servers have found the large majority carrying file-operation patterns prone to path traversal. A meaningful share of tested servers are vulnerable to command injection or server-side request forgery, and there are documented, disclosed cases of tool description poisoning, where the attack lives in the text a model reads to decide what to do rather than in the code the tool actually executes. A closely related failure mode, configuration poisoning, targets the server’s operational baseline directly: stealthy permission changes or altered defaults that persist across sessions and are hard to catch in a normal code review because the malicious logic lives in configuration state, not application code. Multiple high-severity vulnerabilities, including at least one missing-authentication flaw in a major vendor’s own production package, have already been disclosed and patched.
None of that is a reason to avoid MCP. It’s a reason to treat it the way you’d treat any protocol that hands an autonomous caller real privileges inside your systems: skeptically, and with the controls in place before the agent gets access rather than after an incident teaches you why you needed them. In practice that means an explicit, enforced allowlist of vetted tools per agent rather than open discovery of whatever happens to be reachable; authentication on every remote endpoint with no quiet exception carved out for “internal” traffic; centralized, immutable audit logging of every tool call an agent makes; and secrets pulled dynamically from a real secrets manager rather than sitting in a server’s local config where a configuration-poisoning attack can find them. None of this is exotic. It’s the same discipline any experienced integration team already applies to systems with real privileges, applied here to a caller that can now improvise its own sequence of actions.
Here’s what I’d tell a team starting today.
Treat the tool description as reviewed engineering output, not documentation you write last and skim once. Test it against how an agent actually behaves when given it, not just against whether a human reviewer nods along.
Assume composition you didn’t plan for will eventually happen, and design tools to fail safely and legibly when it does, rather than assuming a chain of calls you never tested simply won’t occur.
Put governance in front of capability, not after it. The allowlist, the auth, the audit log, and the secrets manager are the entry price given where the current vulnerability data sits, not optional hardening for later.
And build against the current specification baseline, not whichever example repository you copied six months ago. The stateless core and the authorization changes in the July 2026 spec aren’t cosmetic; targeting an older baseline today is technical debt you’re taking on knowingly, on day one.
MCP earned the “not just another API standard” framing honestly. It didn’t get there by being a cleaner REST, or a nicer SDK, or a better-documented function-calling convention: all real, all incremental. It got there by changing who, or what, is actually doing the integration work at runtime. The parts of that job the protocol doesn’t standardize (how well you describe a capability, how safely your tools behave when composed in ways you never anticipated, and how seriously you take governance before you grant an agent real privileges) are exactly the parts worth taking seriously before you bet production traffic on it.
Enjoyed this article? Sign up for our newsletter to receive regular insights and stay connected.