

Data streams change the operational unit of log storage. Instead of treating a single index as the long-lived container for every event, the platform rotates data into backing indices that are easier to size, query, and retire. For teams running high-volume logs, that shifts tuning from ad hoc shard rescue to policy-driven lifecycle control.
The main architectural dependency is alignment between the template and the lifecycle policy. The timestamp field, index pattern, and ISM policy must match from the first write onward, or rollover and retention will not behave consistently. That makes schema discipline part of the ingestion design, not just a search concern. It also means existing pipelines need a safe migration path if they currently write to conventional indices.
Operationally, the value comes from reducing “index sprawl” without losing observability access. Smaller backing indices improve time-range querying and limit the blast radius of heavy writes, while tier transitions move aged data off hot storage when query demand falls. The trade-off is added policy complexity: teams must decide rollover thresholds, retention windows, and migration timing carefully so automation does not create gaps, premature moves, or unexpected hot-tier pressure.
For platform owners, this pattern is most useful when logs are append-only and lifecycle rules are predictable. It fits environments where ingestion is continuous, historical retention matters, and cost control must be enforced centrally. The implementation effort is less about creating a stream and more about governing the complete path from write routing to storage tiering and validation.
The challenge
While Amazon OpenSearch Service has long provided tools like Index State Management (ISM) for time series data management, many organizations still struggle with implementing optimal patterns for their continuously growing datasets. Common challenges include:- Performance degradation from index growth: As single indices grow unbounded, query latency increases, you might find shard sizes more difficult to manage, and you might experience strain on your cluster resources.
- Manual index management overhead: Without automation, you must invest significant operational effort to manage index lifecycles, rollover, and retention.
- Complex setup: Coordinating index templates, aliases, and ISM policies manually can be error-prone.
- Inefficient resource utilization: All data residing in hot storage regardless of access patterns, leading to unnecessarily high costs.
Solution overview
As illustrated in Figure 1, our solution uses Amazon OpenSearch Service data streams combined with Index State Management to automatically distribute data across multiple indices and manage the data lifecycle. A data stream is an abstraction layer that simplifies time series data ingestion. It provides a single, consistent endpoint for writes while automatically managing multiple backing indices behind the scenes. Instead of writing directly to individual indices, applications write to the data stream, which routes data to the appropriate backing index. Here’s how it works:- Data streams provide a single write index when data is first ingested, which can help streamline time series data ingestion.
- When the backing index ages or grows to meet your defined criteria, ISM automatically performs the rollover operation.
- You can use ISM policies to automatically transition your aged data to different storage tiers based on rules you define and configure.
- You can automate the entire process through rules you define in the index template and ISM policies.
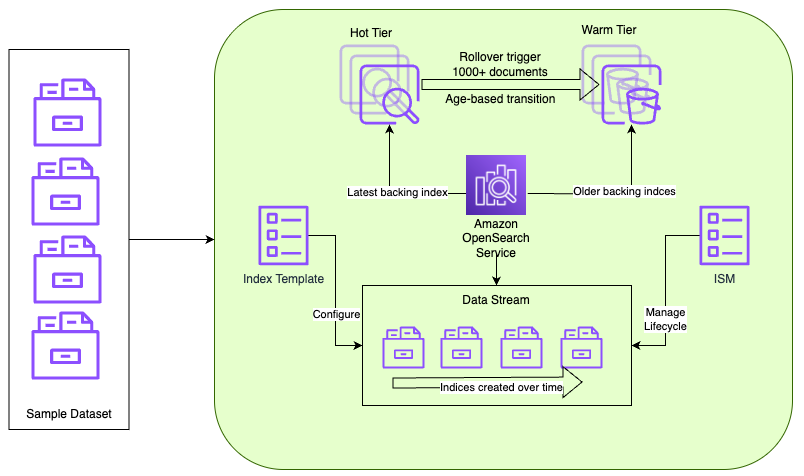 Figure 1 — Time series data workflow using Amazon OpenSearch Service data streams
Data ingests into an index according to your index template configuration. Over time, a data stream creates new indices automatically. Amazon OpenSearch Service manages the lifecycle, transitioning data from hot to warm storage according to the ISM policy configuration you define.
When to use this solution
This approach is ideal when:- You’re ingesting time series data such as logs, metrics, traces, or Internet of Things (IoT) events.
- Your data is append-only and immutable.
- You’re ingesting millions of documents daily with long-term retention requirements.
- You want to reduce storage costs through storage tiering (UltraWarm, Cold storage), as outlined in the blog post Decrease your storage costs with Amazon OpenSearch Service index rollups.
Implementation steps
Prerequisites
Before you begin, make sure that you have the following:- OpenSearch Service domain with UltraWarm nodes (Sample CLI command to create a domain with UltraWarm nodes enabled).
- OpenSearch Dashboards Dev Tools Console.
- Direct API calls using curl or any REST client.
- OpenSearch Dashboards ISM interface (for policy management).
- Log in to OpenSearch Dashboards.
- Navigate to Dev Tools (usually found on the menu under Management).
- Use the interactive console to run the commands.
Section 1: Create data stream
First, create an ISM policy that defines the rules for index rollover and storage tier transitions. The following policy defines two states (hot and warm) and sets rules for when indices transition between them. The policy triggers a rollover when the document count reaches 1,000 and moves indices to warm storage after 2 minutes. Note: The rollover and transitions configurations are only for demo purposes.PUT _plugins/_ism/policies/ds-ism-policy
{
"policy": {
"description": "rollover policy when index is large",
"default_state": "hot",
"ism_template": [
{
"index_patterns": ["webserver-logs-data-stream*"],
"priority": 300
}
],
"states": [
{
"name": "hot",
"actions": [
{
"rollover": {
"min_doc_count": 1000
}
}
],
"transitions": [
{
"state_name": "warm",
"conditions": {
"min_index_age": "2m"
}
}
]
},
{
"name": "warm",
"actions": [
{
"retry": {
"count": 3,
"backoff": "exponential",
"delay": "1m"
},
"warm_migration": {}
}
]
}
]
}
}- Create an index template for the data stream
PUT _index_template/webserver-logs-data-stream-template
{
"index_patterns": ["webserver-logs-data-stream*"],
"data_stream": {
"timestamp_field": {
"name": "timestamp"
}
},
"template": {
"settings": {
"plugins.index_state_management.policy_id": "ds-ism-policy"
},
"mappings": {
"properties": {
"timestamp": {
"type": "date"
}
}
}
}
}- Create data stream
PUT _data_stream/webserver-logs-data-stream- Validate ISM policy mapping
GET _plugins/_ism/explain/webserver-logs-data-streamSection 2: Ingesting data to data stream
In real-world scenarios, log data is typically collected and streamed directly to Amazon OpenSearch Service data streams. However, to demonstrate rollover and migration scenarios in this post, we take a different approach. We first load sample log data into a standard OpenSearch Service index, then reindex and migrate that data to a data stream. To get started, run the commands in the Dev Tools console to create an index and populate it with sample log data.- Reindex existing data
POST _reindex
{
"source": {
"index": "webserver-logs"
},
"dest": {
"index": "webserver-logs-data-stream",
"op_type": "create"
},
"script": {
"source": """
try {
// Validate timestamp field exists and has a value
if (ctx._source.timestamp == null || ctx._source.timestamp.empty) {
ctx.op = 'noop';
}
} catch (Exception e) {
// Skip this document on any error
ctx.op = 'noop';
}
"""
},
"conflicts": "proceed"
}- Monitor index rollover
GET _cat/indices/.ds-*?v&h=index,status,health,pri,rep,docs.count,store.size,creation.date&s=index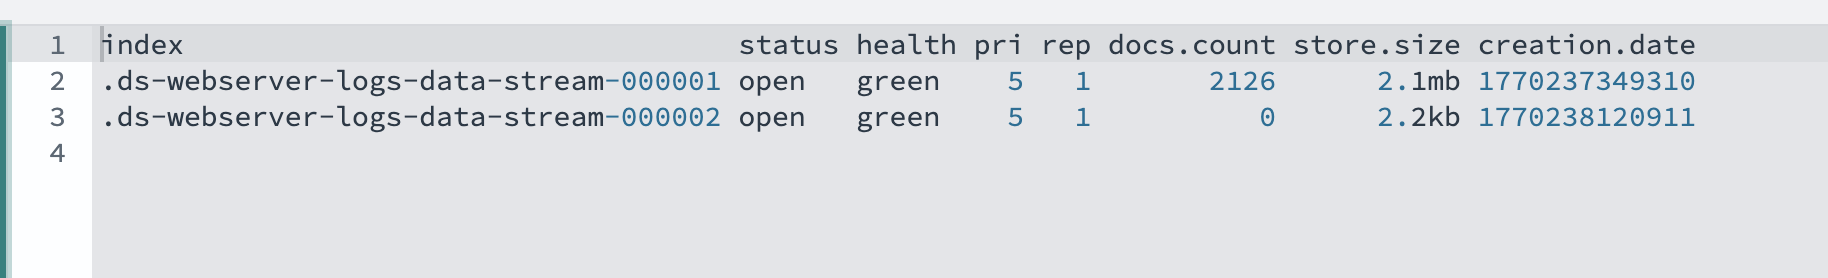 You can also validate this from OpenSearch Dashboards by navigating to Index Management, Data streams, webserver-logs-data-stream.
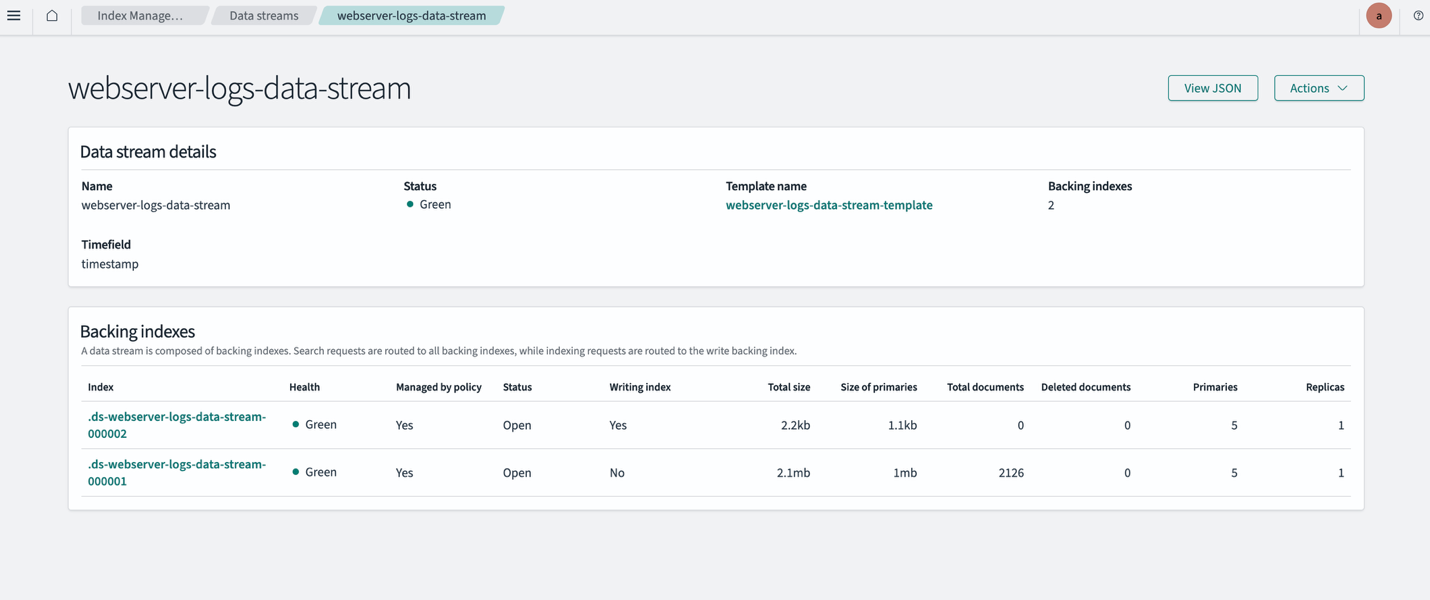 *Figure 2 — Combined view of the _cat/indices CLI output and the OpenSearch Dashboards data stream details, showing a successful index rollover across multiple backing indices*
- Validate warm transition
GET _plugins/_ism/explain/webserver-logs-data-stream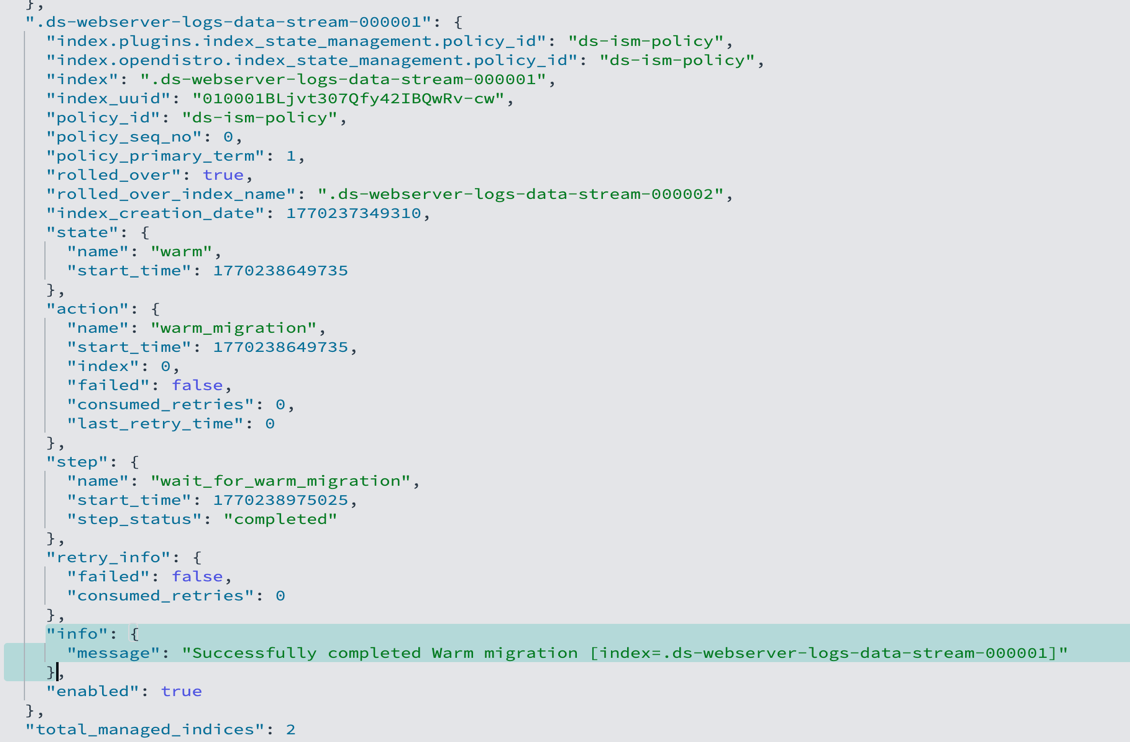
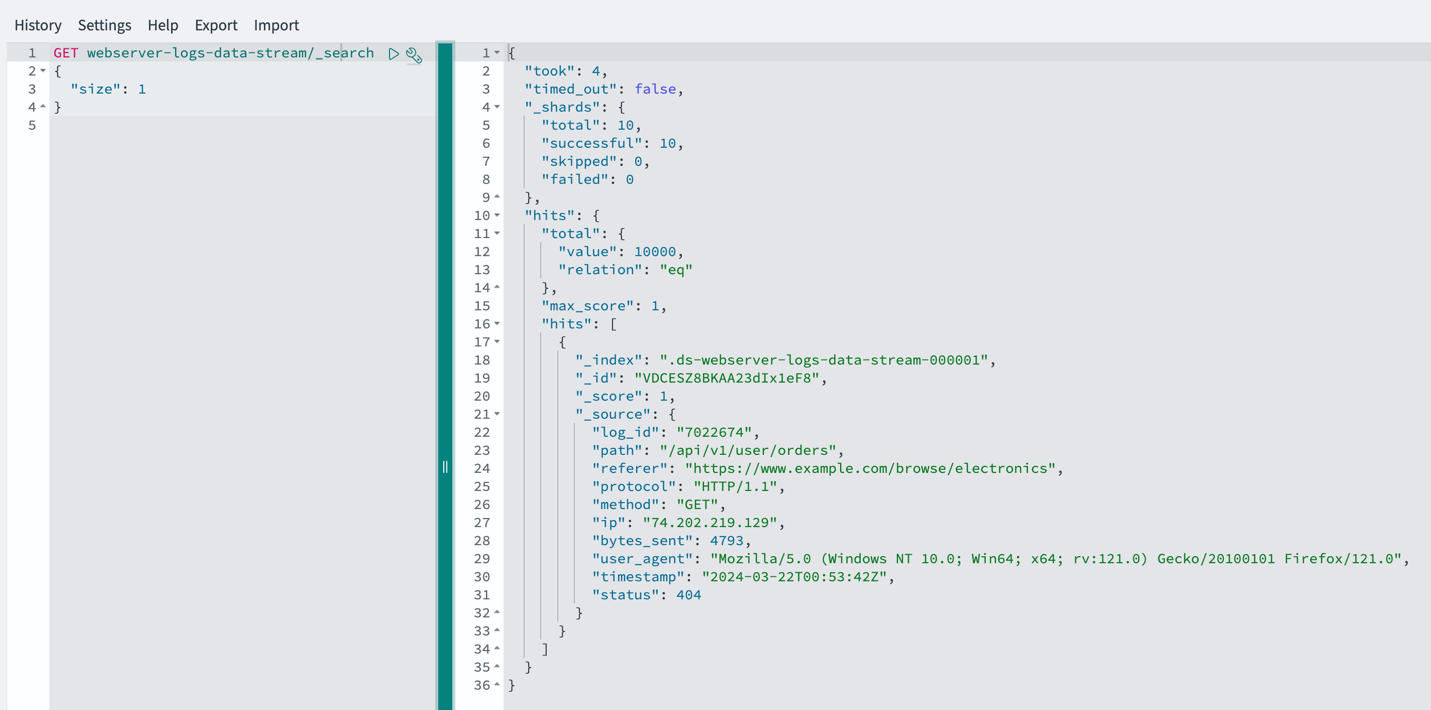
- Verify ingested data
GET webserver-logs-data-stream/_search
{
"size": 1
}
- Clean up
DELETE _data_stream/webserver-logs-data-stream
DELETE _index_template/ webserver-logs-data-stream-templateConclusion
OpenSearch data streams with ISM offer capabilities for managing time series data at scale. Organizations that implement this approach can see improved query performance through distributed load and smaller, time-based backing indices that support efficient time-range queries. Automated index management reduces operational overhead. Storage tiering automatically moves aged data to UltraWarm storage, which significantly lowers costs without sacrificing access to historical data. Combined with better scalability for growing datasets, this solution simplifies index management while delivering improved performance and a more cost-effective, maintainable infrastructure.About the authors
Praveen Krishnamoorthy Ravikumar
Praveen is an Analytics Specialist Solutions Architect at AWS. He helps customers design and implement modern data and analytics platforms that leverage the scalability, flexibility, and innovation of the cloud. He is passionate about solving complex data challenges and enabling organizations to unlock actionable insights from their data.JP Boreddy
JP is a Senior Solutions Architect at Amazon Web Services, based in San Diego, California. He works with ISV customers in the security segment, helping them architect and optimize their workloads on AWS. JP specializes in AI/ML, containers, and cloud infrastructure, with a focus on enabling customers to build scalable, cost-effective solutions. He has been with AWS for over four years.Aswin Vasudevan
Aswin is a Senior Solutions Architect for Security, ISV at AWS. He is a big fan of generative AI and serverless architecture and enjoys collaborating and working with customers to build solutions that drive business value.Kevin Fallis
Kevin is seasoned leader, architect, and developer with experience across many industry verticals and disciplines such as agriculture, ad tech, financial services, networking, security, telecommunications and of course search technologies. His passion helps others leverage the correct mix of AWS services and open-source solutions to achieve success for their business goals. His after-work activities include family, DIY projects, carpentry, horses, playing drums, and all things music.Enjoyed this article? Sign up for our newsletter to receive regular insights and stay connected.