
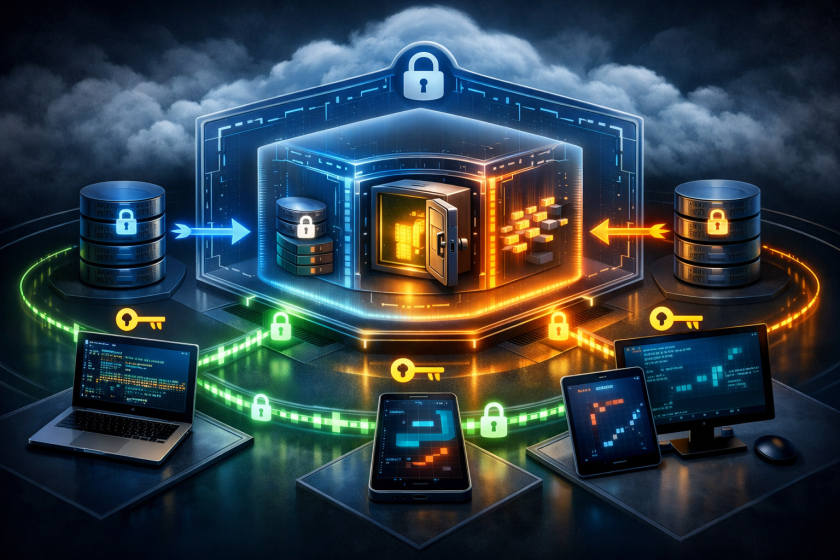
In practice, this kind of server-side memory depends on more than encryption claims. Cross-device continuity means teams will need to think about device enrollment, key recovery, device loss, rotation, revocation and multi-device consistency. If user-held keys are the barrier to provider access, operational resilience becomes a harder problem: how does memory survive hardware replacement, account compromise, or partial trust across personal and managed devices without weakening the privacy model?
There are also important implementation implications for AI product teams. Persistent memory increases the value of context, but also the blast radius of incorrect context, poisoned inputs or stale state. Architects should look closely at enclave boundaries, attestation, auditability, retention controls and how memory is scoped per application, user and task. The core trade-off is clear: stronger privacy through cryptographic isolation can reduce provider visibility, but that same opacity may complicate debugging, compliance operations and abuse detection. The technical success of private AI memory will depend as much on key management and lifecycle controls as on the model itself.
AI is becoming more capable and intuitive — remembering what matters, understanding the world around you, and acting at your direction. Privacy and trust are core to making that possible, ensuring your data stays private and protected as AI systems evolve to provide more continuous assistance across your devices.
Today, we are sharing how we will bring private, server-side memory to our Private AI Compute platform. This breakthrough resolves a longstanding dilemma in modern AI: how to give an assistant long-term continuity across devices while upholding the strict privacy standards typically limited to on-device processing.
Bringing on-device privacy to cloud-scale memory
With this new technical capability, a new persistent memory layer will be able to function like a secure digital vault in the cloud. Under this model, the information needed to assist you is sealed within dedicated, encrypted storage, while the cryptographic keys required to unlock it are held exclusively on your personal devices — ensuring your data is inaccessible to anyone else, even Google.
The diagram below shows how this update to Private AI Compute will work. When an AI model needs to access information to assist you, an authenticated, end-to-end encrypted channel connects your device to a protected, isolated environment in the cloud. That space, or “secure enclave,” temporarily decrypts your data in isolated memory to handle the request, saves any new context, and immediately encrypts it, keeping your information private as if it never left your device.

By combining hardware-enforced secure enclaves, encrypted channels, and per-user databases shielded by device-derived encryption keys, this architecture ensures your data stays fully private and under your control.
This evolution is necessary to meet the computing needs of the AI era. Local, on-device processing has historically been the gold standard for privacy — but frontier AI models often require far more computing power than any one device can provide. Bringing advanced AI to personal assistants means solving how to tap into the power of the cloud while ensuring personal data can remain as protected as if it never left your device.
To that end, we previously introduced our Private AI Compute platform, allowing users to process complex tasks in hardware-isolated cloud enclaves. Until now, that technology — along with similar solutions across the industry — was strictly “stateless,” meaning it wiped all context the moment a task ended. Workarounds, like having AI save a list of personal facts and preferences, aren’t enough to support the rich, continuous experiences people expect from personal AI. Making that level of assistance possible means engineering a way for cloud-scale AI to securely retain context over time and across devices.
Building trust, looking ahead
Imagine pulling up assembly instructions on your laptop that you previously viewed through smart glasses, or resuming complex conversations between mobile and web. Private AI Compute is designed to make that kind of seamless assistance possible – keeping the pieces it needs to remember safely locked away. But the user’s trust in that system’s privacy is also important.
Building that trust starts with transparency. That’s why, alongside our updated technical whitepaper, we’re publishing a tamper-proof public record of our server software. Devices running Private AI Compute will be able to verify that our software is authentic and unaltered before sending any personal data. In addition, we’re providing an update on our technical methods, including the results of an independent audit by a leading cybersecurity firm. By sharing these resources, we invite the broader privacy community to verify Private AI Compute’s protections.
Adding private, persistent memory to Private AI Compute shows how deeply personal assistance can be private by design. We invite the community to review the updated Private AI Compute Technical Brief and our system architecture, security proofs, and verification protocols.
Acknowledgements
This research was co-developed by Google DeepMind, Platforms & Devices, Core and Cloud teams. We would also like to thank Four Flynn, Jay Yagnik, and David Kleidermacher for their executive sponsorship of this work.
Enjoyed this article? Sign up for our newsletter to receive regular insights and stay connected.